The kokkekunst.no site
A static news site with no database and no server of its own. Its build fails, rather than warns, when a story breaks the rules.
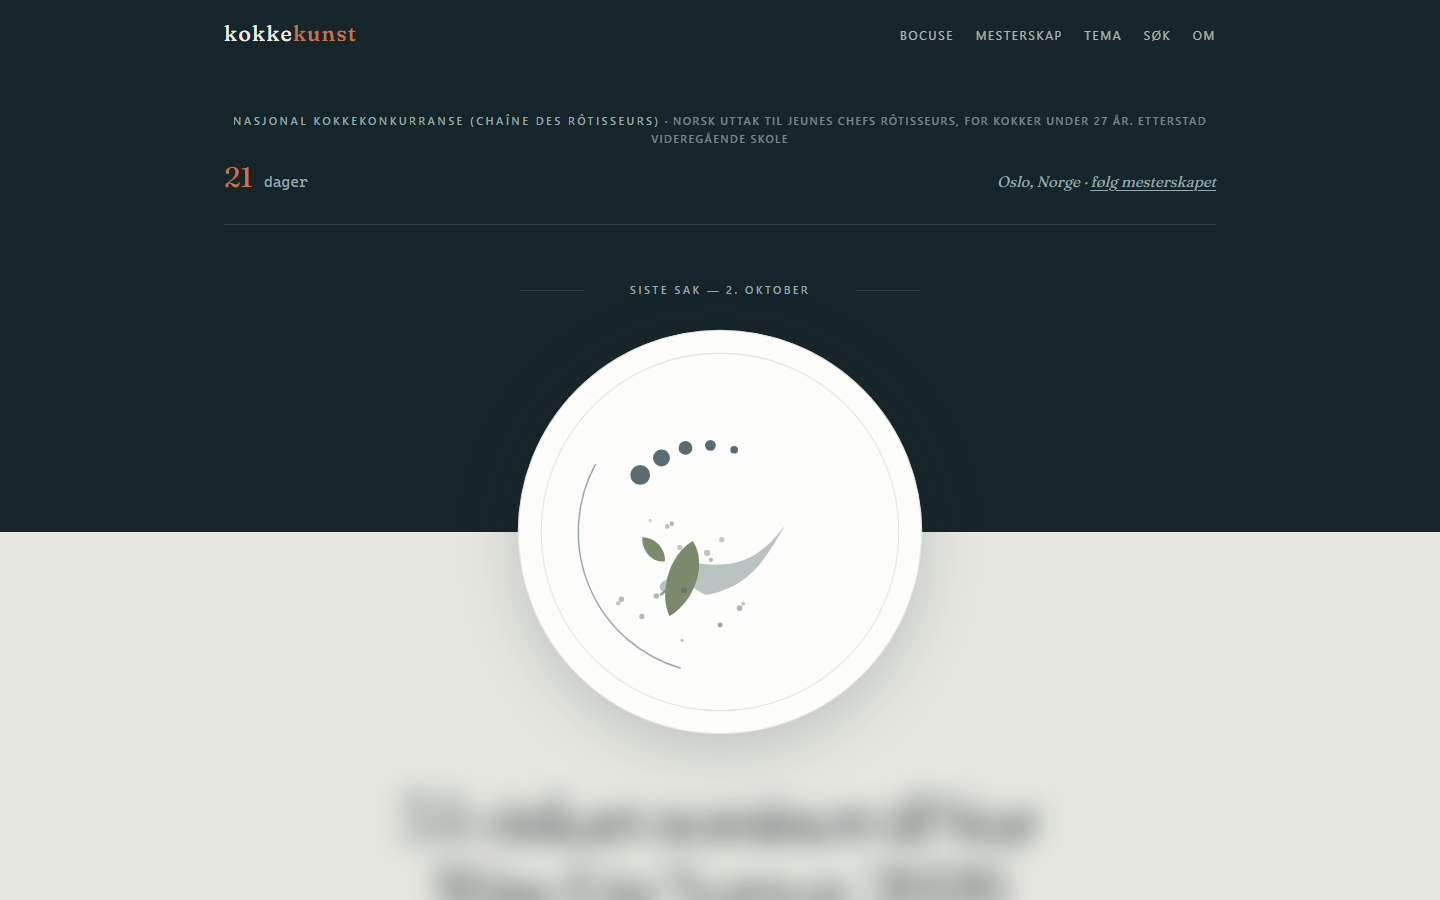
The front page of kokkekunst.no on 3 October 2026. Headlines, leads and source lines are blurred, because the stories can name people.
What it is
This is the part of kokkekunst.no that readers actually see: the front page, the stories, the championship calendar, the search. It is a set of plain files on Cloudflare’s network. There is no database behind it, no login, and no application to attack. The README puts it bluntly: if you are tempted to add “just a small endpoint”, don’t.
Nobody writes stories in this repository. The newsroom engine commits them here as markdown files, one commit per publish. Since October it also commits the images and videos for Instagram posts. Each Reel adds a commit of 2 to 3 MB. Since 10 October the engine makes a story’s Reel before the story is published. It releases the Reel eight minutes after publishing, because Pages has to finish building the site first.
How it works
Every push to the main branch starts a build on Cloudflare Pages. Astro turns the markdown into pages, and Pagefind builds the search index.
Before anything goes live, four checks run, and each one fails the whole build instead of printing a warning. A story must have at least one source. Every link in its text must be one of those sources. Its slug must match its file name. Any image must have a licence file next to it.
The rules for what a story may contain live in a single schema file. The same file, byte for byte, sits in the engine, and both sides check that the copies have not drifted apart.
Nearly no story has a photo, so the design relies on typography modelled on a restaurant menu. Each story gets a drawn plate generated from its slug, which is also its sharing image.
Search and sharing
On 6 October Claude worked through a six-point search order. Every page type now has structured data that uses shared identifiers for the organisation and the website. The search page runs a query taken straight from the address. The robots tag allows full-length snippets, and the RSS feed now holds the 30 newest stories instead of 50.
The about page now opens with a fact box in Henning’s own words, and its first sentence is also the summary in llms.txt. A separate command reads the built files and checks all six points, including that the two sentences match. The news sitemap has its own test that uses one fresh story and one old one.
From 7 October, new slugs are cut at a word break. Google had shown addresses that ended in half a word. Published slugs stay as they are.
People and results
Since 24 September the site has had a page for each person with at least two sourced facts, twelve in all. The championship pages show results and the podium. Results are still entered by hand from the organiser’s own results page.
Google was slow to find the person pages. Since 3 October, stories have listed the people they mention in their structured data. Person page titles now lead with the person’s main result.
What we expected, and what happened
Read it like a code review. Each removed line is something we expected, from a plan, a spec, a README or a code comment. The added line under it is what the history shows actually happened.
Expected: The link check, written as a plugin that runs when Astro parses markdown, would stop any story with a link that is not in its sources.
Happened: With a warm build cache Astro skipped parsing, the plugin never ran, and a build passed with a foreign link. A second check now reads the files raw from disk on every build and has the final say.
Expected: The README says the site has no database, no API routes and no Pages Functions. The canonical tag also pointed to www.
Happened: Google ranked the pages.dev copy above www for at least one search on 18 September, ignoring the canonical tag. A small function now answers that address with a permanent redirect. The README still says there are no Pages Functions.
Expected: The first DNS document recommended an ALIAS record as the way to serve the bare domain.
Happened: That was a wrong premise: Cloudflare Pages only attaches a bare domain that is a zone on the Cloudflare account. A CNAME there would also have broken the domain's email. The rewritten document says so.
Expected: The first design had a dark serving surface under a light dining room, and a sitemap that left out pages marked noindex.
Happened: The dark surface never rendered dark, because one style rule sat outside its media query, so the whole site was one flat grey. The sitemap filter ended in a condition that was always true, so it filtered nothing. Both were fixed in the design round on 30 August.
Expected: The linking round on 28 September made the tag pages point to the person pages, added footer links on every page and put the news sitemap into the sitemap index. It came after Search Console showed that Google did not know the twelve person pages.
Happened: On 3 October, five days later, Search Console still showed none of the person pages as indexed, and it found no page linking to them. Searches for finalists' names landed on single stories instead. The same day, stories started listing the people they mention in their structured data, and person page titles now lead with the person's main result.
Expected: The search review of 13 to 16 September listed last-modified dates in the sitemap as done.
Happened: A check on 6 October found 13 of the 90 addresses in the sitemap with no date, among them the about page, the sources page and person pages with no stories of their own. Every address now gets one: the date the content carries, then the last commit on its source files, then the build time.
Expected: The engine's status screen would show visits to kokkekunst.no from the cookie-free analytics.
Happened: The analytics data sits per account, and the account is shared with vibeapp.win. Claude's query filtered only on time, so vibeapp.win pages turned up among the kokkekunst.no pages and the totals were too high. Since 6 October only the kokkekunst.no hostnames are counted.
Page history
- First version of this page.
- On 3 October 2026 the kokkekunst.no site linked each story to the person pages in its structured data and gave person pages clearer titles, after Search Console showed that none of the twelve person pages were indexed; this page now covers person pages and championship results.
- 4 October 2026: we checked the page against the site's repository; the only commit since the last update was the 3 October person-page change, which the page already covers, so nothing changed.
- 2026-10-08: added the 6 October search round (structured data, sitemap dates, RSS, the about page fact box, new checks), the Instagram media now committed to the site, word-break slugs, and a fix to how visits were counted.
- On 12 October 2026 we updated the commit count: the site had no commits from 8 to 12 October. We also added that since 10 October the newsroom engine makes each story's Reel before publishing, then releases it about eight minutes later while the site builds.